
CONTINUE EXPLORINGConnect the context.
The input distribution is the research problem
Real project drawings contain furniture, annotations, incomplete enclosures, inconsistent scales and mixtures of vector and raster content. A pipeline evaluated on clean architectural plans cannot be assumed to retain its performance on rasterised smart-home drawings. The relevant question is whether the output remains usable after those irregularities have propagated through recognition.
Our FY2026 investigation therefore used company drawings and expert annotations as its experimental base. The initial corpus comprised 65 training and 17 validation drawings, with 984 expert room polygons across 14 classes. That is a representative working corpus for this investigation, not a benchmark large enough to establish general performance across the built environment.
Factorise geometry and semantics
A joint model must decide both where a room ends and what the room is. Error inspection showed that these questions failed independently: a recognisable bedroom could have an unusable boundary, while a clean region could receive the wrong class. The adopted formulation separates single-class room segmentation from vision-language typing of the resulting regions.
The multi-class baseline reported mask mAP50 around 0.30; the single-class geometry task reported 0.70. These are different tasks. Removing classification changes the metric’s meaning, so the two scores do not constitute a 40-point like-for-like improvement. The relevant end-to-end result is the assembled space model, assessed against expert polygons.
Topology is a geometric computation
Once room polygons exist, adjacency can be derived from shared-boundary proximity under a tolerance, and containment from polygon nesting. The resulting graph makes relationships explicit without adding a second learned topology detector. This matters downstream: a device on a shared wall is related to two spaces even when a point-in-polygon test cannot assign it meaningfully to either.
Tolerance is an engineering parameter, not a universal constant. Rasterisation, scale and boundary error change what “near” means. The graph must therefore remain inspectable alongside the geometry from which it was derived. A plausible room label cannot repair a broken spatial relationship.
| Candidate explanation | Recorded observation | Architectural consequence |
|---|---|---|
| Joint geometry and typing | Boundary and class errors separated under inspection. | Use distinct geometry and semantic tasks. |
| Model capacity | Larger configuration gave no recall gain. | Do not assume scaling the backbone resolves the current residual. |
| Small-room resolution | Tiling fragmented large rooms. | Investigate alternatives to the rejected tiling strategy. |
| Implicit structure | Corridor residuals and flood-fill were insufficient. | Investigate explicit wall and opening structure. |
Choose an operating point for correction cost
Default inference settings over-produced candidate rooms. A sweep of confidence thresholds and polygon suppression made the precision–recall trade-off explicit. At confidence 0.45 and suppression 0.4, precision was 0.712 and recall 0.622. Lowering confidence to 0.25 later moved recall to approximately 0.70, at the expense of precision.
The change follows how engineers correct a plan: deleting a spurious polygon can be less expensive than drawing a missed room from scratch. It is a product operating-point decision, not evidence that the model learned more. The 0.712 precision and the approximately 0.70 recall belong to different configurations and must not be presented as a single result.
Use negative results to isolate the constraint
A larger backbone with increased input resolution and augmentation produced no recall gain in the recorded comparison. Tiled inference, introduced to recover small rooms, fragmented larger rooms at tile boundaries and degraded the assembled model. A classical flood-fill route failed on unclosed raster linework; on vector inputs it needed door detection to close openings.
A further-data comparison moved from a 65/17 training/validation split to 88/16 without an observed outward shift in the precision–recall frontier. Because the validation set changed, this is not a strictly controlled scaling result. Together, these experiments redirected attention toward structural information rather than supporting a general claim that larger models or more data cannot help.
Boundary-ambiguous spaces expose a missing layer
Residual errors concentrated in entries, corridors, dining and outdoor areas, and in small rooms lost to down-sampling. Many of these spaces are defined by their surroundings rather than by independent enclosing walls. Constructing corridors as the leftover footprint after subtracting enclosed rooms did not recover the regions an engineer would draw.
The evidence points toward explicit walls, doors and openings as a likely constraint on boundary-ambiguous spaces. That structural layer was identified but not solved within the reporting period. The tiled experiment also leaves small-room down-sampling unresolved: rejecting one remedy does not eliminate the underlying problem.
The output is a revisable engineering artefact
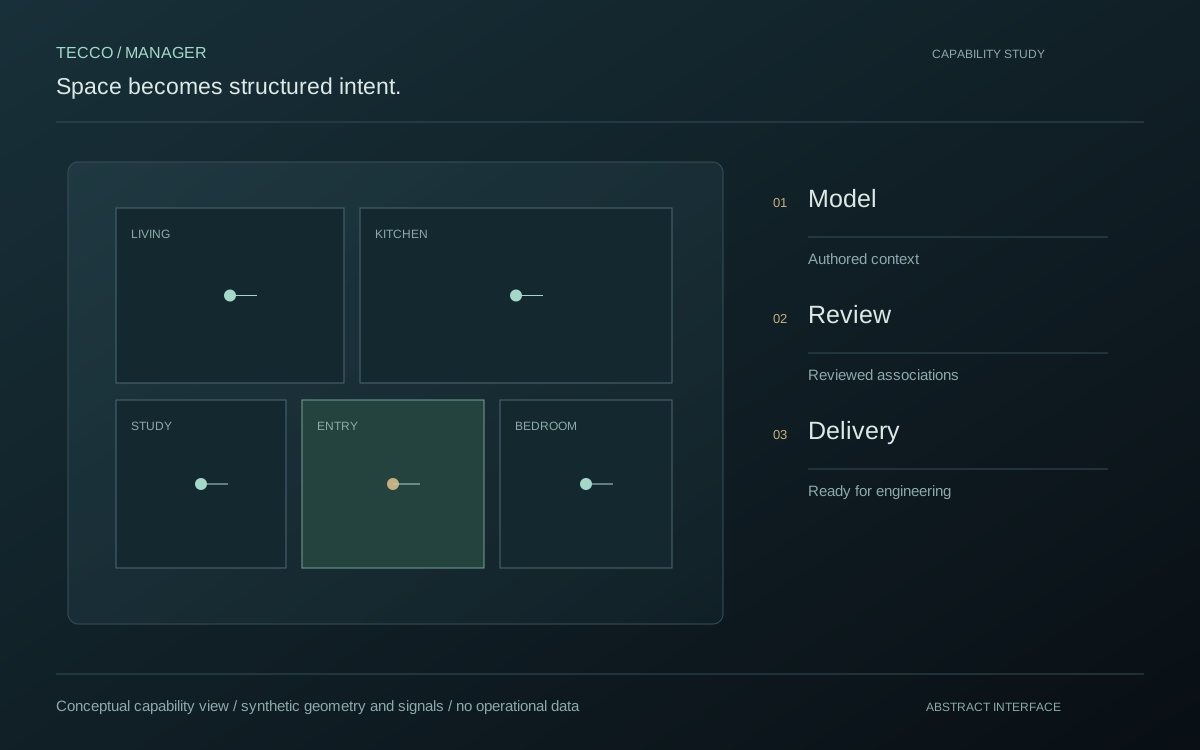
Manager supplies the review surface, with room polygons, device markers and spatial relationships available for correction. Corrected annotations can return as weighted examples. This creates the data path for an iterative system, but the existence of a correction pipeline is not itself proof of improved model accuracy.
Future evaluation should measure geometric overlap, missed regions, topological consistency and human correction effort separately. The practical objective is a reliable substrate for engineering decisions, with each stage’s uncertainty still visible.